Setup
In what follows, “write and implement” means that we suggest that you write the function in pseudocode first, and then implement your function.
We are providing starter code for this assignment here. Please download the sandpile folder and add it to your python/src directory. This folder contains the following files:
datatypes.py: do not edit this file; it declares theBoardtype, a rectangular list of lists of integers.helper_functions.py: do not edit this file; it contains utilities such ascontains(),deep_copy_board(),num_rows(),num_cols(), andmake_empty_board().serial.py: place the functions for the serial sandpile simulation here.parallel.py: place the functions for the parallel sandpile simulation here.drawing.py: do not edit this file; it contains drawing functions that convert boards into animation frames.main.py: after implementing all simulation functions, you will edit this file to run both simulations.
Make sure you have the pygame, imageio, and numpy modules installed. If not, install them by running the following in your terminal:
pip3 install pygame-ce "imageio[ffmpeg]" numpy(macOS/Linux)pip install pygame-ce "imageio[ffmpeg]" numpy(Windows)
The autograders for this assignment are currently hosted on Cogniterra.
Sandpiles: a discrete diffusion simulation with a CMU connection
Imagine a huge two-dimensional checkerboard on which you place piles of coins of various heights on some of the squares (at most one pile per square). Consider the following toppling operation.
Definition: topple(r, c): if square (r, c) has four or more coins on it, move one coin from (r, c) to each of its four neighbors to the north, south, east, and west (diagonal neighbors do not count). If square (r, c) has fewer than four coins, do nothing.
Repeatedly applying this toppling operation represents a discrete diffusion process, and as we will see, it produces some beautiful and surprising patterns.
A configuration of coins is stable if every square has fewer than four coins on it, so that there are no more topple operations to perform. If we topple all the cells of the board repeatedly, then we will eventually reach a stable configuration. A surprising theorem states that for a given initial configuration, the order in which we perform topples does not affect the stable configuration that we reach.
For example, say that we start with a pile of 1,000 coins on the center square of a 200 × 200 board. However we perform topple operations, we will obtain the stable configuration in the figure below, in which cells with zero coins are black, cells with one coin are dark gray, cells with two coins are light gray, and cells with three coins are white. Each cell is represented by a single pixel.
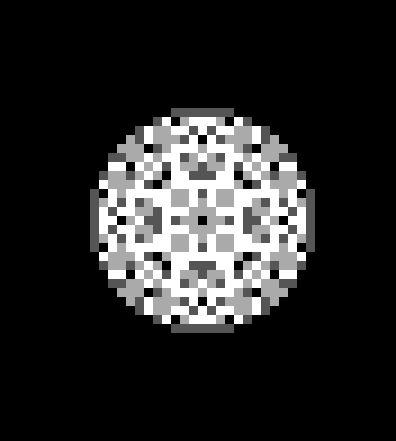
If we instead start with 100,000 coins on the center square and no coins elsewhere, then after applying all possible topple operations, we obtain the stable configuration below (assuming that the board is large enough that coins never reach its edges).
What is amazing about this process is that as we increase the number of coins on the central square, the final stable configuration becomes a more and more detailed version of the same pattern. When we reach 230, or about one billion coins, we obtain the board shown below.
Sandpiles have a Carnegie Mellon connection, which you can read more about here. To explore a gallery of stable sandpile boards, check out this page.
Serial and parallel sandpiles
In this assignment, we will implement the sandpile diffusion system with a couple of twists.
First, when you see the images above, a natural thing to wonder is what the intermediate steps look like. As you will see, the answer is “beautiful.”
Second, this assignment offers a wonderful opportunity to practice parallel programming. You will first implement the sandpile simulation serially, which will show you how much stronger you have become as a programmer. You will then extend your program into a parallel program, using the serial version to test the parallel one, and you will time the two approaches to see under what conditions the parallel program runs faster.
Rather than toppling one square at a time, we will update every cell of the board simultaneously in each generation. A single update step replaces the value of each cell (r, c) as follows:
new[r][c] = old[r][c]
            + (coins received from the four neighbors of (r, c))
            - (coins sent outward if old[r][c] >= 4)
We repeatedly apply this update rule until the board is stable, recording every intermediate board so that we can animate the evolution of the sandpile.
Note: If (r, c) lies on the boundary of the board, we model the topple operation as if the coins fall off the edge of the board. We do not keep track of the coins that fall off, but we should still remove four coins from (r, c) even if it lies on the boundary. If we do not make this assumption, then some inputs will cause our program to run forever.
Learning objectives
After completing this assignment, you will be able to:
- explain the sandpile model and how it provides an alternative perspective on diffusion, self-organization, and systems built from local updates;
- build a modular simulation engine, beginning with a correct serial implementation and extending it into a multiprocessing design;
- measure and interpret program performance, including timing the serial and parallel versions and understanding why speedups may or may not occur;
- apply core ideas of parallel programming, including dividing work across processes, sharing read-only data, assembling partial results, and coordinating process boundaries;
- analyze how initial conditions affect parallel behavior, recognizing that speedup depends not only on the structure of an algorithm but also on input size and how quickly the board stabilizes.
Function hierarchy
The highest-level functions in this assignment are simulate_sandpiles(), which runs the simulation serially, and simulate_sandpiles_parallel(), which runs it in parallel using Python’s multiprocessing module. Both functions start from an initial board, repeatedly apply the update rule until the board is stable, and return the full list of boards. The functions in serial.py fit together as follows.
simulate_sandpiles(initial_board)
  ├─ final_boards = [deep_copy_board(initial_board)]
  ├─ while not is_converged(current board):
  │     ├─ new_board = update(current board)
  │     │    └─ for each cell (r, c):
  │     │          new[r][c] = old[r][c]
  │     │                      + number_of_coins_in(b, r, c)
  │     │                      - number_of_coins_out(b, r, c)
  │     └─ append new_board to final_boards
  └─ return final_boards
The parallel version divides the rows of the board into chunks and hands one chunk to each worker in a pool of processes.
simulate_sandpiles_parallel(initial_board, num_procs)
  ├─ create one multiprocessing.Pool of size num_procs
  ├─ final_boards = [deep_copy_board(initial_board)]
  ├─ while not is_converged_multi_procs(pool, current board, num_procs):
  │     ├─ new_board = update_multi_procs(pool, current board, num_procs)
  │     └─ append new_board to final_boards
  ├─ close the pool
  └─ return final_boards

is_converged_multi_procs(pool, b, num_procs)
  ├─ chunks = make_row_chunks(num_rows(b), num_procs)
  ├─ each worker runs check_chunk_for_instability() on one chunk
  └─ return True only if every chunk is stable

update_multi_procs(pool, b, num_procs)
  ├─ chunks = make_row_chunks(num_rows(b), num_procs)
  ├─ each worker runs update_subboard_single_proc(b, row_start, row_end)
  │     └─ returns (row_start, the updated rows of its chunk)
  ├─ splice each chunk into a new board at row_start
  └─ return the new board
Best practices
Build a correct serial implementation first
Do not begin the parallel portion until your serial code is complete and passes the autograders. Your serial implementation serves as both the ground truth for correctness and the design template for the parallel version.
Good serial structure leads to good parallel structure
The most effective parallel solutions look “almost serial.” Each worker performs a small serial computation on its own section of the board, and the parent process coordinates the workers and assembles their results. Keeping your serial code modular will make your parallel design modular as well.
Check conservation of mass
Unless coins fall off the edge of the board, the total number of coins should remain constant from one generation to the next. If the total changes unexpectedly, the culprit is almost always incorrect boundary handling or a mismatch between the serial and parallel updates.
Running your program
Once you have implemented all the functions below, complete main.py so that it parses four command-line arguments, builds two copies of a starting board with create_board(), runs simulate_sandpiles() on one and simulate_sandpiles_parallel() on the other (with num_procs equal to os.cpu_count()), and writes each animation to a video. The program is called as follows.
python3 main.py <board_width> <num_coins> <random|central> <cell_width>
For example, the following command creates a 50 × 50 board with 4,000 coins on the central square, draws each cell 10 pixels wide, and writes the files serial.mp4 and parallel.mp4, which show the pile collapsing and spreading over time.
python3 main.py 50 4000 central 10
Try timing each simulation with time.time(). On a large central board, such as python3 main.py 300 20000 central 4, you should see the parallel simulation finish faster than the serial one once the work per step outweighs the overhead of coordinating processes. On small boards, the opposite may happen. Why?
Simulating sandpiles serially
A sandpile board is stable if every element in the board is less than 4.
Code Challenge: Write and implement a functionis_converged(b: Board) -> boolthat takes aBoardobjectbas input and returnsTrueifbis stable andFalseotherwise.
Note: The following functions are provided for you behind the scenes in the autograder:assert_rectangular(b: Board) -> None,num_rows(b: Board) -> int,num_cols(b: Board) -> int.
Next, we compute how many coins leave a given cell in a single generation.
Code Challenge: Write and implement a functionnumber_of_coins_out(b: Board, r: int, c: int) -> intthat takes aBoardobjectband integersrandcas input and returns the number of coins that will be toppled fromb[r][c]and sent to neighboring squares.
Note: For each test case, the autograder calls your function on every cell of the board and produces a new board whose cell (r, c) isnumber_of_coins_out(b, r, c).
We also need to know how many coins arrive at a cell from its four neighbors.
Code Challenge: Write and implement a functionnumber_of_coins_in(b: Board, r: int, c: int) -> intthat takes aBoardobjectband integersrandcas input and returns the number of coins thatb[r][c]will receive as a result of toppling from its neighboring cells.
Note: As withnumber_of_coins_out(), the autograder calls your function on every cell of the board. A functioncontains(b: Board, r: int, c: int) -> bool, which returnsTrueif (r, c) lies within the bounds ofbandFalseotherwise, is provided for you in the starter code and behind the scenes in the autograder.
In a single generation of our sandpile diffusion process, each cell’s number of coins decreases by the number of coins that it topples and increases by the number of coins received from topple operations of the cells in its von Neumann neighborhood.
Code Challenge: Write and implement a functionupdate(b: Board) -> Boardthat takes aBoardobjectbas input and returns theBoardobject resulting frombafter a single generation of diffusion.
Note: The following functions are provided for you behind the scenes in the autograder:number_of_coins_out(b: Board, r: int, c: int) -> int,number_of_coins_in(b: Board, r: int, c: int) -> int,contains(b: Board, r: int, c: int) -> bool,assert_rectangular(b: Board) -> None,num_rows(b: Board) -> int,num_cols(b: Board) -> int.
We are now ready to write our highest-level serial function.
Code Challenge: Write and implement a functionsimulate_sandpiles(initial_board: Board) -> list[Board]that takes aBoardobjectinitial_boardas input and returns a listfinal_boardsofBoardobjects whose first element isinitial_board, wherefinal_boards[i]is obtained fromfinal_boards[i-1]by applyingupdate(), and where the final element offinal_boardsis the stable final configuration of the sandpile process.
Note: This function should run serially. The following functions are provided for you behind the scenes in the autograder:is_converged(b: Board) -> bool,update(b: Board) -> Board,deep_copy_board(b: Board) -> Board,number_of_coins_out(b: Board, r: int, c: int) -> int,number_of_coins_in(b: Board, r: int, c: int) -> int,contains(b: Board, r: int, c: int) -> bool,assert_rectangular(b: Board) -> None,num_rows(b: Board) -> int,num_cols(b: Board) -> int.
Simulating sandpiles in parallel
When we parallelize work on a two-dimensional array over its rows, we need to partition the rows into approximately equally sized “chunks.” To do so, we produce a list of pairs (start, end), where each pair represents a half-open interval of row indices, according to the following rules.
- Each pair (
start,end) represents the rowsstart,start + 1, …,end - 1. - The chunks must partition the row indices 0, 1, …,
total_rows - 1with no gaps and no overlaps. - The number of chunks should be equal to the minimum of
num_procsandtotal_rows. - All chunks should be the same size, except that any leftover rows are given to the final chunk.
For example, if total_rows is 10 and num_procs is 3, then the chunks should be (0, 3), (3, 6), and (6, 10).
Code Challenge: Write and implement a functionmake_row_chunks(total_rows: int, num_procs: int) -> list[tuple[int, int]]that takes integerstotal_rowsandnum_procsas input and returns a list of pairs (start,end) dividing the rows of a board into chunks according to the rules above.
We will use our chunks to check whether a board is stable in parallel.
Code Challenge: Write and implement a functionis_converged_multi_procs(pool: multiprocessing.Pool, b: Board, num_procs: int) -> boolthat takes a pool of worker processespool, aBoardobjectb, and an integernum_procsindicating how many row chunks to split the work into. It should returnTrueifbis stable andFalseotherwise, where the work is parallelized acrosspoolusingnum_procsrow chunks.
Note: The pool is created by the caller (in the autograder, by the autograder itself). Do not create a new pool or closepoolinside your function; just dispatch work to it, for example withpool.starmap(), and return.
Note: The following functions are provided for you behind the scenes in the autograder:make_row_chunks(total_rows: int, num_procs: int) -> list[tuple[int, int]],check_chunk_for_instability(b: Board, total_cols: int, chunk_start: int, chunk_end: int) -> bool,assert_rectangular(b: Board) -> None,num_rows(b: Board) -> int,num_cols(b: Board) -> int. The functioncheck_chunk_for_instability()is also provided inparallel.py; it returnsFalseif any cell in rowschunk_startthroughchunk_end - 1has four or more coins, andTrueotherwise.
Next, we write the function that each worker runs to update its own chunk of rows.
Code Challenge: Write and implement a functionupdate_subboard_single_proc(b: Board, row_start: int, row_end: int) -> tuple[int, Board]that takes aBoardobjectband integersrow_startandrow_endas input. It should return a tuple whose first element isrow_startand whose second element is aBoardcontaining the result of updating one generation of the sandpile process for the rows ofbwith indicesrow_startthroughrow_end - 1.
Note: Do not updatebin place, which would overwrite data that other processes may need to read; instead, create new rows. We returnrow_startalongside the new rows so that the caller knows where to splice the chunk back into the assembled board. The following functions are provided for you behind the scenes in the autograder:number_of_coins_out(b: Board, r: int, c: int) -> int,number_of_coins_in(b: Board, r: int, c: int) -> int,contains(b: Board, r: int, c: int) -> bool,assert_rectangular(b: Board) -> None,num_rows(b: Board) -> int,num_cols(b: Board) -> int.
We can now update an entire board in parallel.
Code Challenge: Write and implement a functionupdate_multi_procs(pool: multiprocessing.Pool, b: Board, num_procs: int) -> Boardthat takes a pool of worker processespool, aBoardobjectb, and an integernum_procsas input. It should return theBoardresulting frombafter a single generation of diffusion, where the work is parallelized acrosspoolusingnum_procsrow chunks. The returned board must have the same dimensions asb, andbitself must not be changed.
Note: As withis_converged_multi_procs(), do not create or close a pool inside this function. The following functions are provided for you behind the scenes in the autograder:update_subboard_single_proc(b: Board, row_start: int, row_end: int) -> tuple[int, Board],make_row_chunks(total_rows: int, num_procs: int) -> list[tuple[int, int]],make_empty_board(r: int, c: int) -> Board,number_of_coins_out(b: Board, r: int, c: int) -> int,number_of_coins_in(b: Board, r: int, c: int) -> int,contains(b: Board, r: int, c: int) -> bool,assert_rectangular(b: Board) -> None,num_rows(b: Board) -> int,num_cols(b: Board) -> int.
If you made it this far, congratulations! Our highest-level parallel function follows directly from update_multi_procs() and is_converged_multi_procs().
Code Challenge: Write and implement a functionsimulate_sandpiles_parallel(initial_board: Board, num_procs: int) -> list[Board]that takes aBoardobjectinitial_boardand an integernum_procsas input and returns a listfinal_boardsofBoardobjects whose first element is a deep copy ofinitial_board, wherefinal_boards[i]is obtained fromfinal_boards[i-1]by applyingupdate_multi_procs(), and where the final element offinal_boardsis the stable final configuration of the sandpile process.
Note: Your function is responsible for creating onemultiprocessing.Poolof sizenum_procsat the start of the simulation, reusing it across every call toupdate_multi_procs()andis_converged_multi_procs(), and closing it before returning. Do not changeinitial_board, and never modify a board after appending it tofinal_boards. The following functions are provided for you behind the scenes in the autograder:update_multi_procs(pool: multiprocessing.Pool, b: Board, num_procs: int) -> Board,is_converged_multi_procs(pool: multiprocessing.Pool, b: Board, num_procs: int) -> bool,deep_copy_board(b: Board) -> Board.